Skip to Main Content
Lightning Talk Intermediate

Building great datasets on your mother tongue with Open-Weight models

Proposal status is Withdrawn
Session Description
  • Since Sarvam is planning to release some open-weight models during June. I want to use that to create nice high quality synthetic datasets for my mother tongue

  • In native languages like malayalam, the amount of good open-source datasets is very less. The amount of data let's say for Malayalam for ASR and TTS datasets was just about 50-100 hours when I started training models.

  • We all know as amount of data increases, the accuracy of models proporitonately increase. Also you can feed special entities to be generated like special entities like locations, names, organization names like FOSS United etc.

Key Takeaways
  • Learn how to create synthethic data with Open-weight models

  • Why native language datasets matter for model performance and cultural relevance

  • Challenges in low-resource languages and how to overcome them with synthethic data from open-weight models.

References

Session Categories

Knowledge Commons (Open Hardware, Open Science, Open Data etc.)

Which track are you applying for?

Open Data Devroom

Speakers
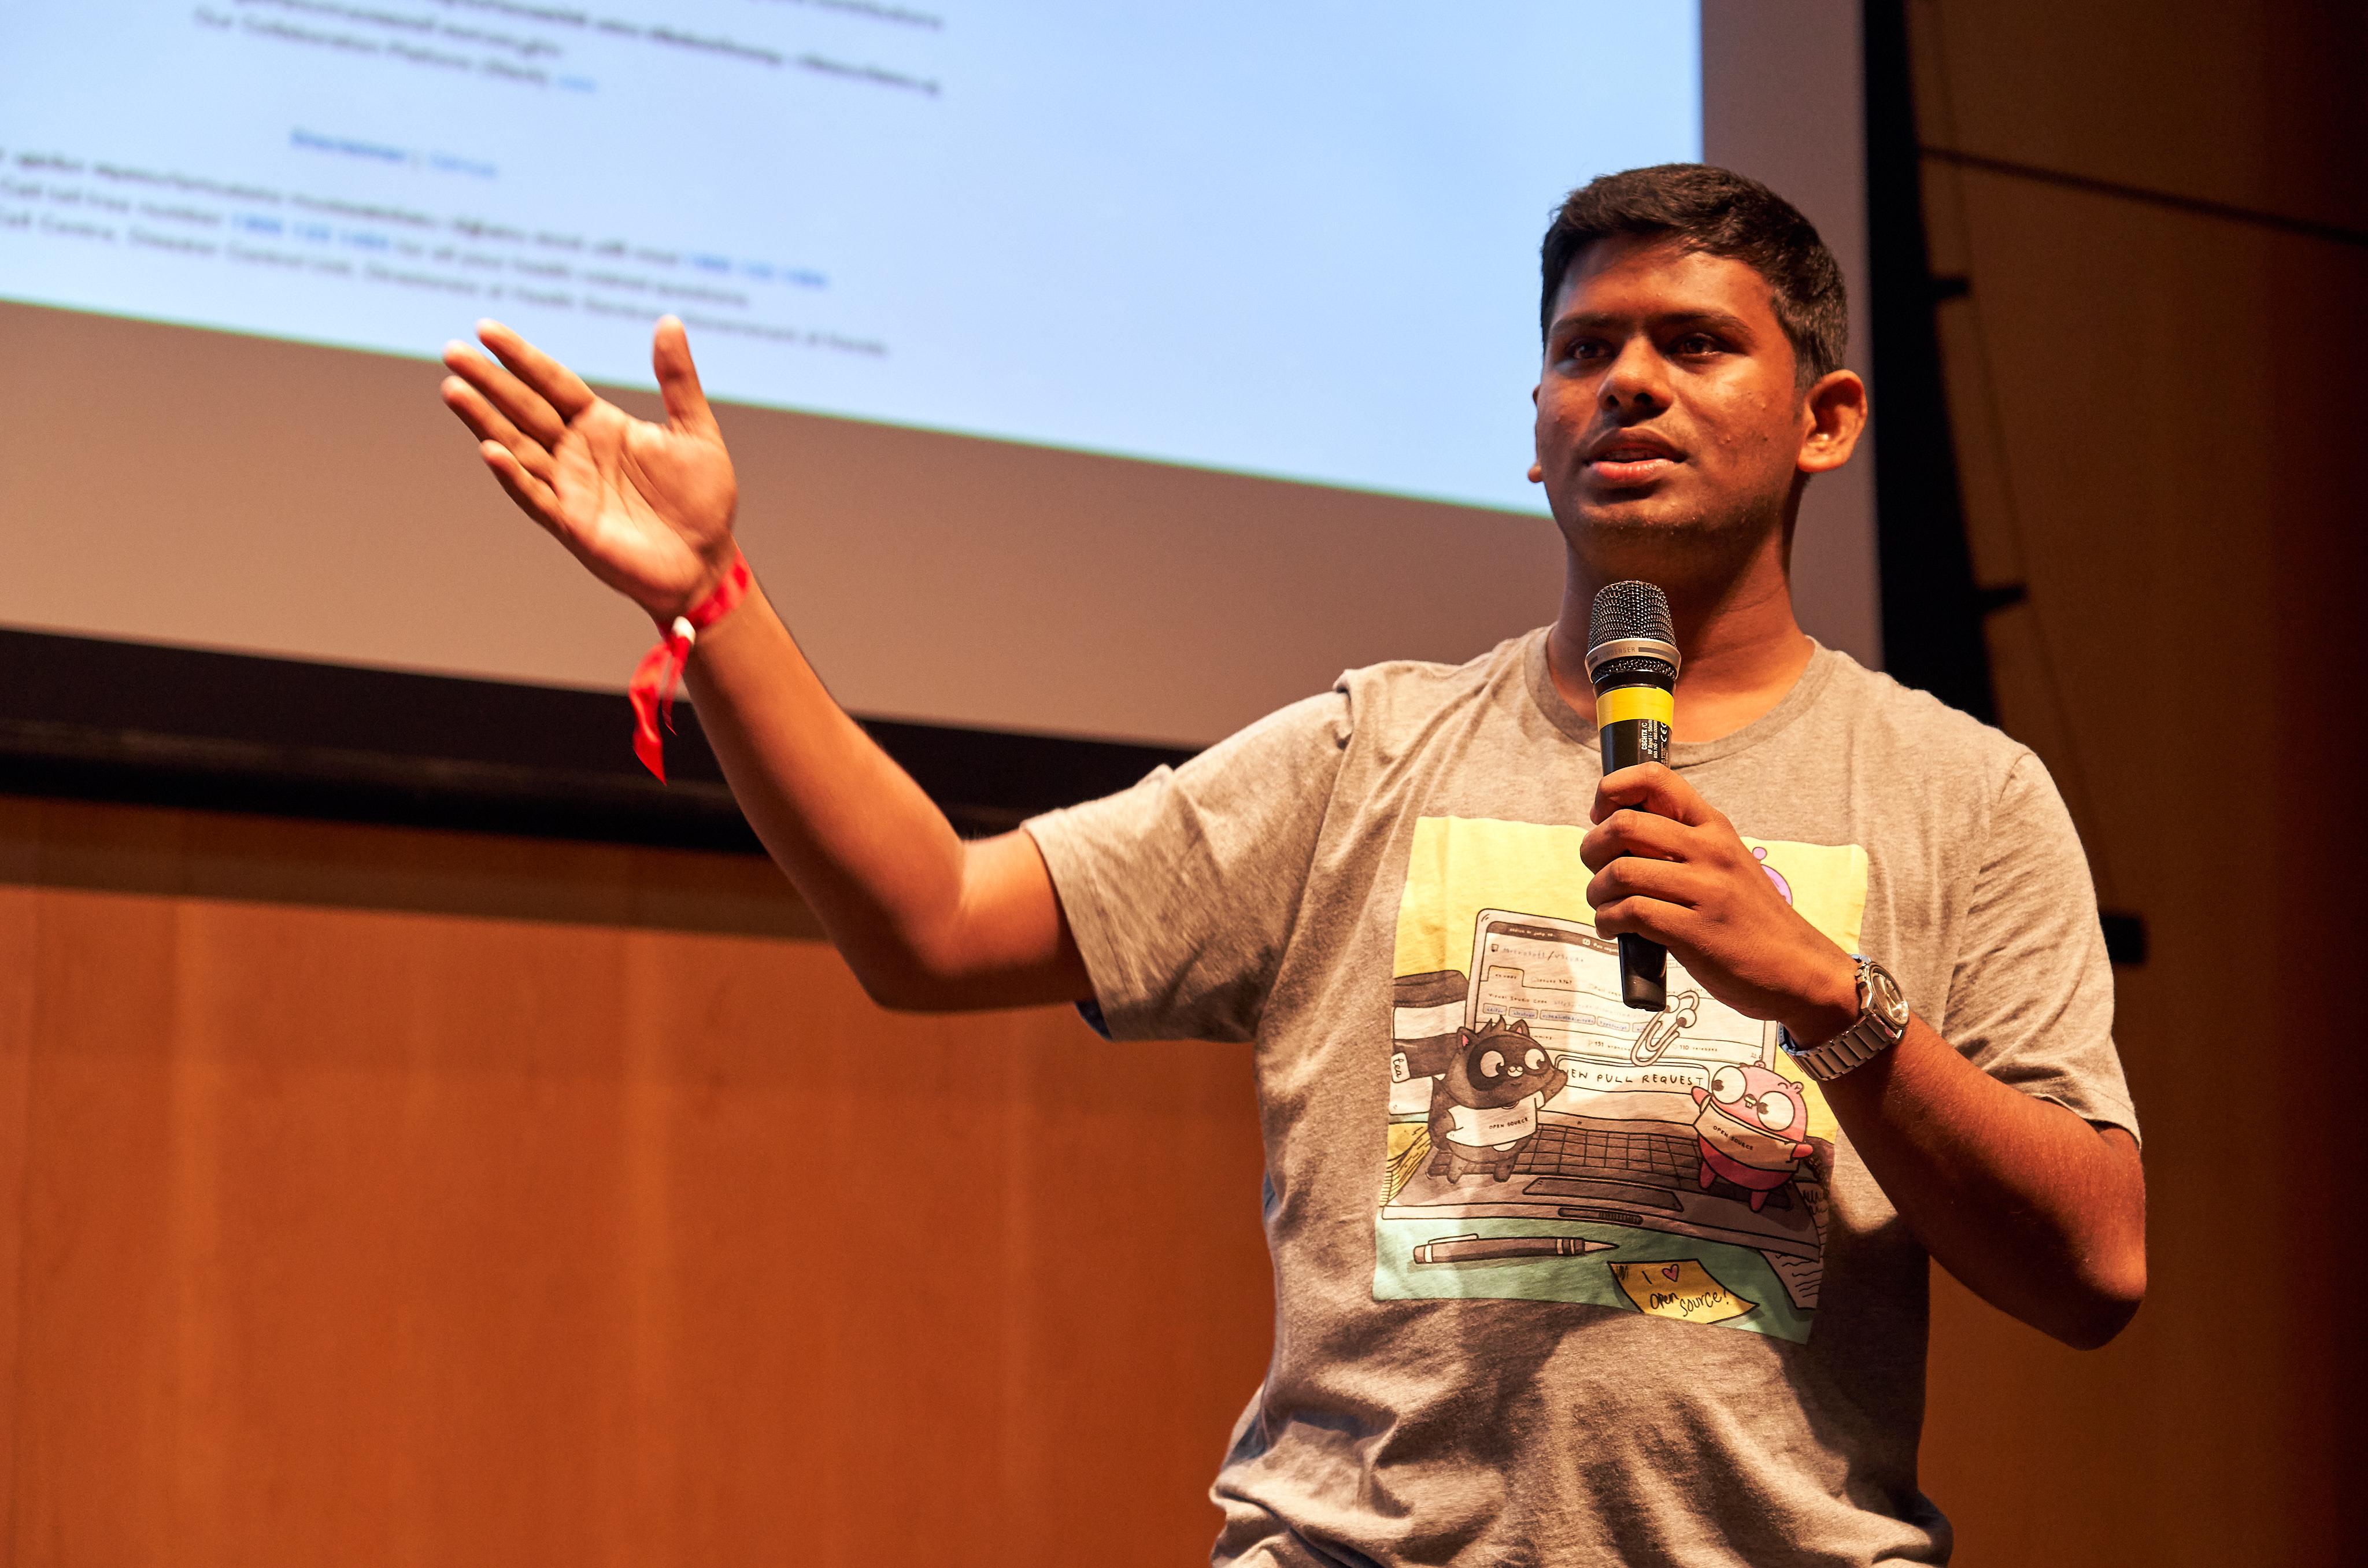
Kurian Benoy
Kurian Benoy ML Engineer | Sarvam

I am working as an ML Engineer building Full-Stack GenAI @ Sarvam.ai. I have multiple years of experience in Python and Machine learning experience. I have contributed to various open source organizations like Swathanthra Malayalam Computing, FOSSASIA, Keras, DVC, HuggingFace, fast.ai, CloudCV etc.